
Kyeongyoon Lee
M.S. Student
AIM Lab, SKKU
Seoul, South Korea
lky3685@skku.eduAbout Me
I am Kyeongyoon Lee, an M.S. student at AIM Lab, Sungkyunkwan University (SKKU). I received my bachelor’s degrees in Statistics and Computer Science from the University of Seoul. My research explores how multimodal AI systems can listen, see, and reason more efficiently.
Research Direction
I am interested in capable and efficient multimodal models that understand long and dynamic real-world contexts.
My research interests include:
- Multimodal Models for joint reasoning across audio, vision, and language.
- Token Compression for reducing computation and memory while preserving useful evidence.
- Video Understanding through temporal representations and memory mechanisms.
News
Publications
-
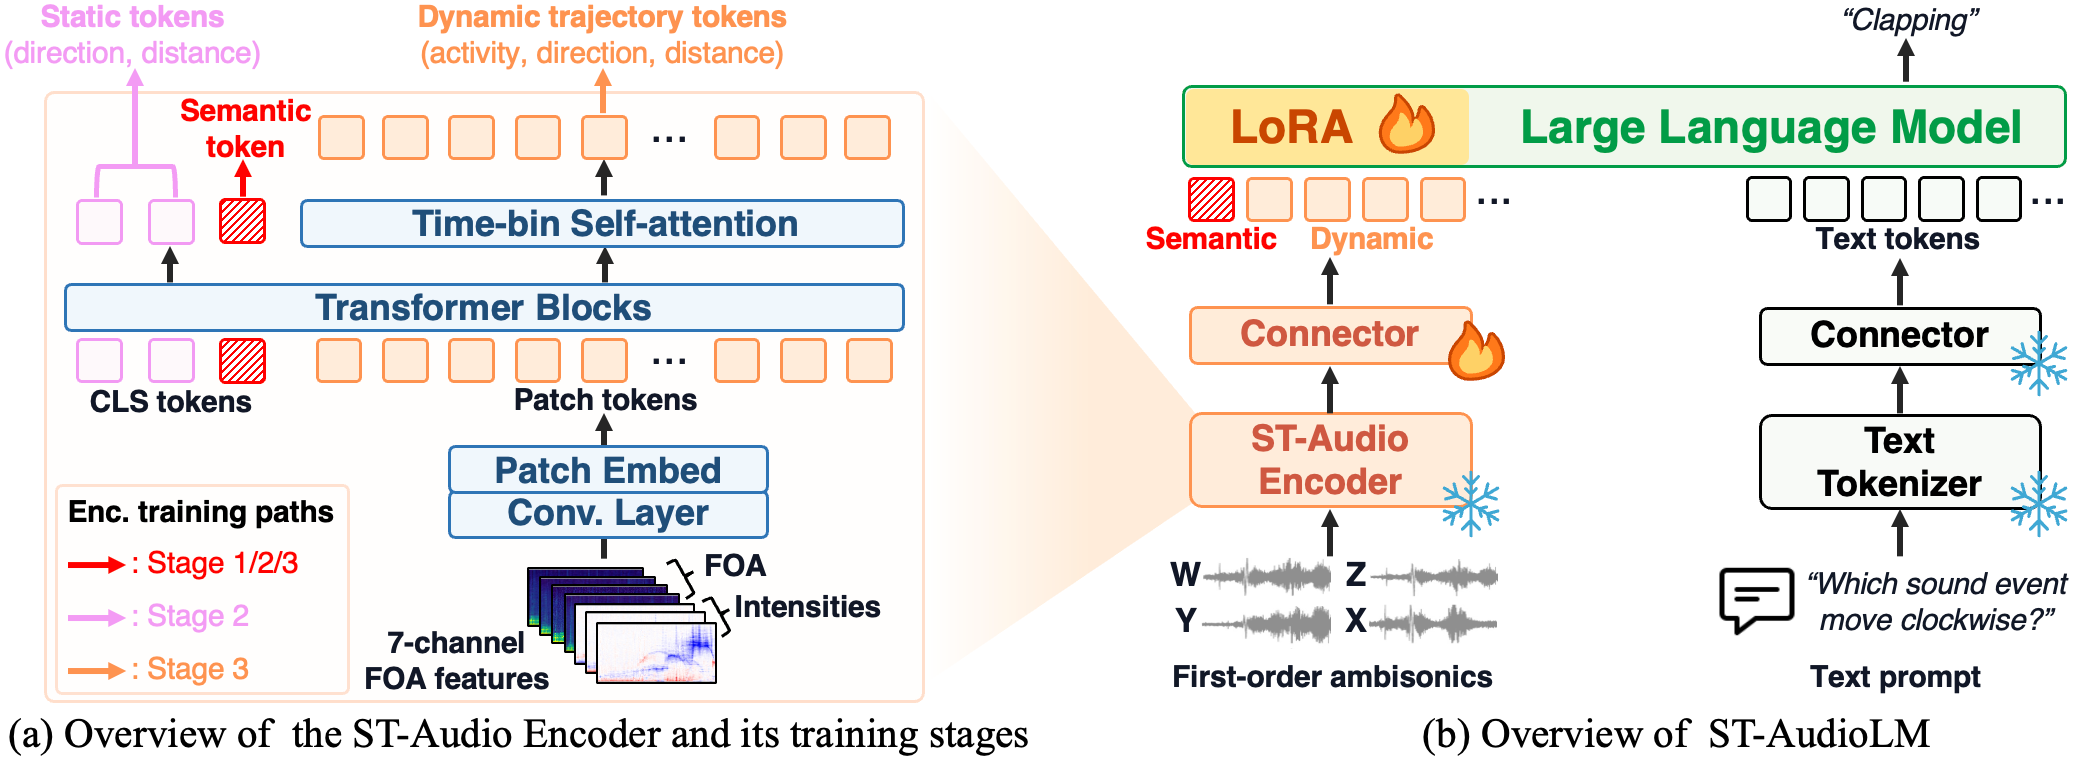
🔎 How can language models understand moving sound sources across space and time?
 EMNLP
Spatio-Temporal Audio Language Modeling for Dynamic Sound Sources
Empirical Methods in Natural Language Processing (EMNLP), 2026. Main Conference.
-
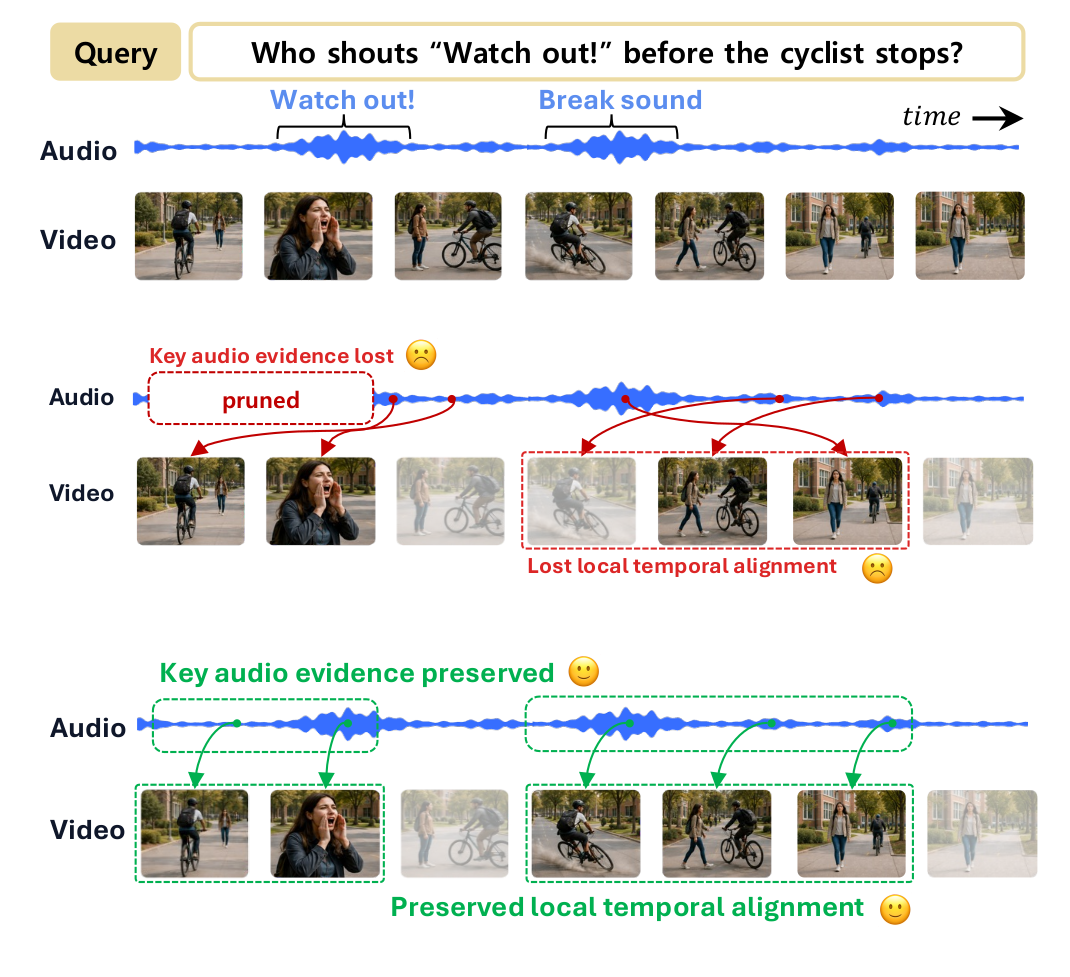
🔎 Can audio-visual dynamics identify the tokens an Omni-LLM should preserve?
 arXiv
Deferred Audio Pruning with Local Audio-Visual Dynamics for Omni-LLMs
arXiv preprint, 2026.
TL;DR A two-stage, training-free framework that preserves information-dense audio before the LLM, compresses video with local audio-visual dynamics, and prunes low-relevance multimodal tokens after query-conditioned interactions emerge.
-
🔎 Can reusable multimodal memory retrieve precise moments without training?
 KDD Workshop
Hierarchical Multimodal Memory for Training-Free Video Moment Retrieval
RespMultimodal’26: Responsible Multimodal Foundation Models for Knowledge Discovery, KDD 2026 Workshop.
TL;DR Builds reusable hierarchical memory from visual captions and ASR, then uses query-aware proposals and multimodal re-ranking to retrieve precise video moments without training.
Domestic
GPT and Stable Diffusion-based Reading Activity Service
SeYun Bae*, , JinSu Lee, Hogyun Jeon, Hyunggu Jung
KSC 2023 Undergraduate Division · *equal contribution
Background
Education
- 2026.02 — PresentM.S. in Immersive Media Engineering, AIM Lab, Sungkyunkwan University (SKKU)
- 2018.03 — 2024.08B.S. in Statistics & B.E. in Computer Science, University of Seoul (UOS)
Experience
- 2025.09 — 2026.02Lab Intern, Department of Immersive Media Engineering, SKKU
- 2025.03 — 2025.06Undergraduate Research Program, KAIST School of Computing · Prof. Oh Tae-Hyun
- 2024.01 — 2025.03Loan Comparison Platform Team, Nonghyup Bank
- 2023.06 — 2023.12Undergraduate Research Intern, Time-series TFT ML, Department of Statistics, UOS
- 2023.01 — 2023.04DataHub Intern, Humax Mobility
Honors & Awards
- AWS Certified Solutions Architect – Associate (C03)
- Shinhan Big Data Hackathon Award
- Hanium Contest ICT Company and Media CEO Award
- KSC 2023 Undergraduate Division Encouragement Award